
How to Remove Duplicate Rows from a CSV File
How to find and remove duplicate rows in a CSV export correctly — choosing the right match columns and deciding which copy to keep.
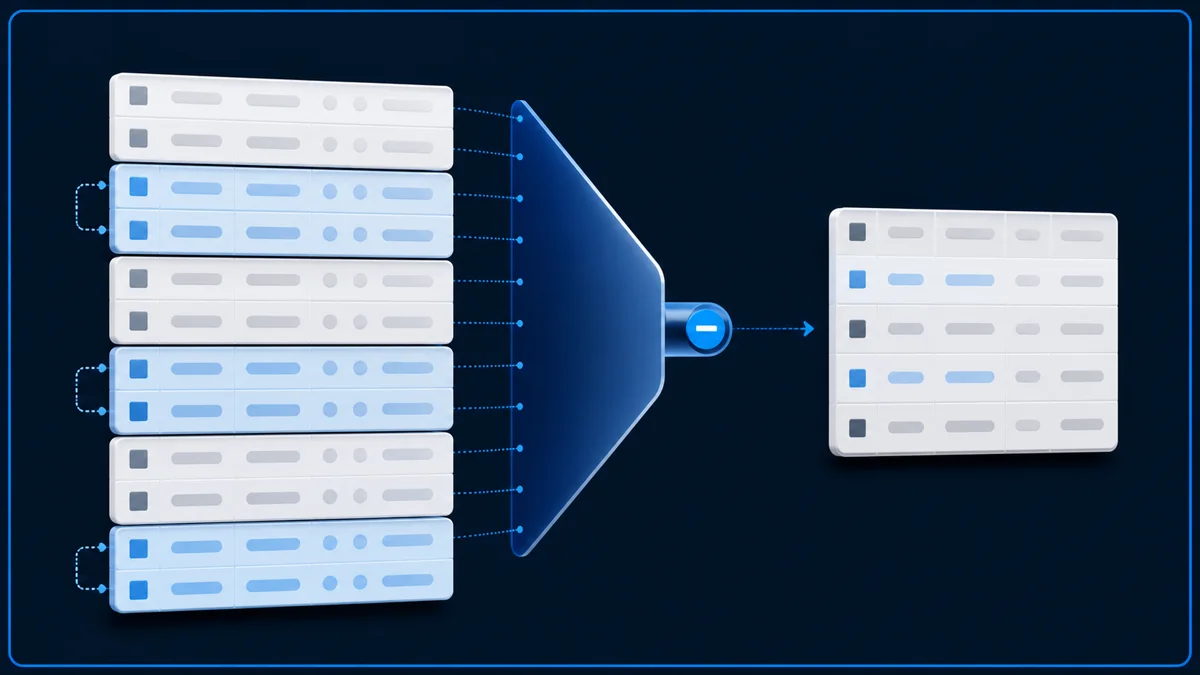
Remove duplicate rows from one CSV directly in your browser without uploading the file, up to 500 MB. The shipped limit was checked for correct results on five different kinds of file, three times each (15 runs total).
That 15-run check used five file shapes: typical data, many different values in the match columns, long match values, very wide rows, and duplicate-heavy data using keep last. Each shape was run three times and checked for correct output. The hardest 500 MiB case was the one with many different match values: its three runs took 43.1, 57.9, and 85.7 minutes and needed about 1.472 GiB of temporary disk space on your own computer. That evidence backs the current limit shown on the tool page, but this kind of file can take a long time and needs enough free disk space.
Duplicate rows creep into CSV exports for mundane reasons: a form submitted twice, a sync job that ran twice, or a spreadsheet export that included the same record from two source systems. Before you can trust a file for import, you need to remove the duplicates — correctly, not just the obvious exact-match ones.
Exact duplicates vs. logical duplicates
An exact duplicate is a row that is exactly the same as another in every field. Those are easy to catch. A logical duplicate is trickier: two rows that represent the same real-world record but differ slightly, such as the same customer with two different phone numbers on file, or the same product with a typo in the name.
Deciding what counts as "the same record" is a business decision, not a technical one — it depends on which column, or combination of columns, reliably identifies a unique entity in your data.
Choosing match columns
| Data type | Strong key | Weak key (avoid alone) |
|---|---|---|
| Customers | first name | |
| Products | SKU | product title |
| Companies | domain / tax ID | company name |
When no single column is reliable on its own, match on a combination — for example, name plus date of birth, or company plus billing address. Matching on too broad a combination produces false positives; matching on too narrow a combination produces false negatives.
Test your match rule on a sample before running it on the full file. A key that's too loose can merge two different customers into one; a key that's too strict can leave real duplicates behind.
What counts as a duplicate
The tool treats two rows as duplicates only when every selected key column has the same trimmed value. Whitespace at the start or end of a key cell is ignored, so two rows that differ only by surrounding spaces are still a duplicate. Casing and punctuation inside the cell are not normalized — "Acme Corp" and "acme corp." are different keys.
When you select more than one key column, two rows match only when every selected column matches. The current size limit is 500 MB per file. The work stays on your device — nothing is uploaded.
- 01
Upload one CSV file.
Choose the file with the duplicate rows. Nothing is uploaded — the file is read and processed in your browser.
- 02
Choose one or more columns for duplicate matching.
Pick the columns that together identify a unique record, such as email alone, or company plus contact name. Selecting the wrong column throws a parse error rather than silently producing a wrong result.
- 03
Keep the first or last occurrence.
Keep first preserves whichever row appeared earliest in the file. Keep last preserves the most recent entry. Pick the one that matches how your file is sorted and which copy carries the data you trust.
- 04
Review the duplicate groups and cleaned preview.
The tool shows how many duplicate groups were found and a preview of the cleaned file before you download. This is the moment to confirm the key rule actually matched what you intended.
- 05
Download the cleaned file or removed rows.
Both files are generated: one with the duplicates removed and one with everything that was filtered out. The source file is never modified.
Keep first, or keep last?
Once duplicates are grouped, you need a rule for which copy survives.
If the duplicate copies contain different values, the keep-first versus keep-last guide explains how the current row order affects which copy survives.
- 01
Keep first
Preserves whichever row appeared earliest — useful when the file is sorted oldest to newest and you want the original record.
- 02
Keep last
Preserves the most recent entry — useful when later rows represent corrections or updates.
- 03
Review manually
If neither rule fits, inspect the duplicate groups before deciding. An automatic rule can silently discard good data.
Always keep the removed rows
A responsible duplicate-removal process doesn't just delete rows — it exports what was removed alongside the cleaned file, so you can spot-check the decision and recover a row if the matching rule was too aggressive. The removed-rows file uses the same column order and delimiter as the source, so it can be opened or re-merged without further work. If a row is removed by mistake, copy it back from that file rather than re-running the cleanup on a fresh source.
Remove CSV duplicatesSee the transformation
Repeated records become a reviewable clean file.
Repeated rows are removed from the clean file and kept easy to review.
✓ Clean file keeps one copy
Need to do this now?
Remove CSV duplicatesRelated tools
Open the tool this guide is about, or explore a related one.
- Clean and fix CSV files — no uploadRepair common CSV problems including wrong delimiters, uneven rows, empty lines, whitespace, BOM markers, and duplicate headers.
- Compare CSV files online freeCompare two CSV files and review added, removed, and changed rows directly in your browser.
- CSV column mapper and renamerRename, reorder, and remove CSV columns before importing data into a CRM, store, database, or accounting system — without uploading your file.