
How to Fix a Broken or Malformed CSV File
How to diagnose malformed CSV structure: uneven rows, duplicate headers, stray whitespace or empty rows, BOM issues, delimiter mistakes, and damaged quoting.
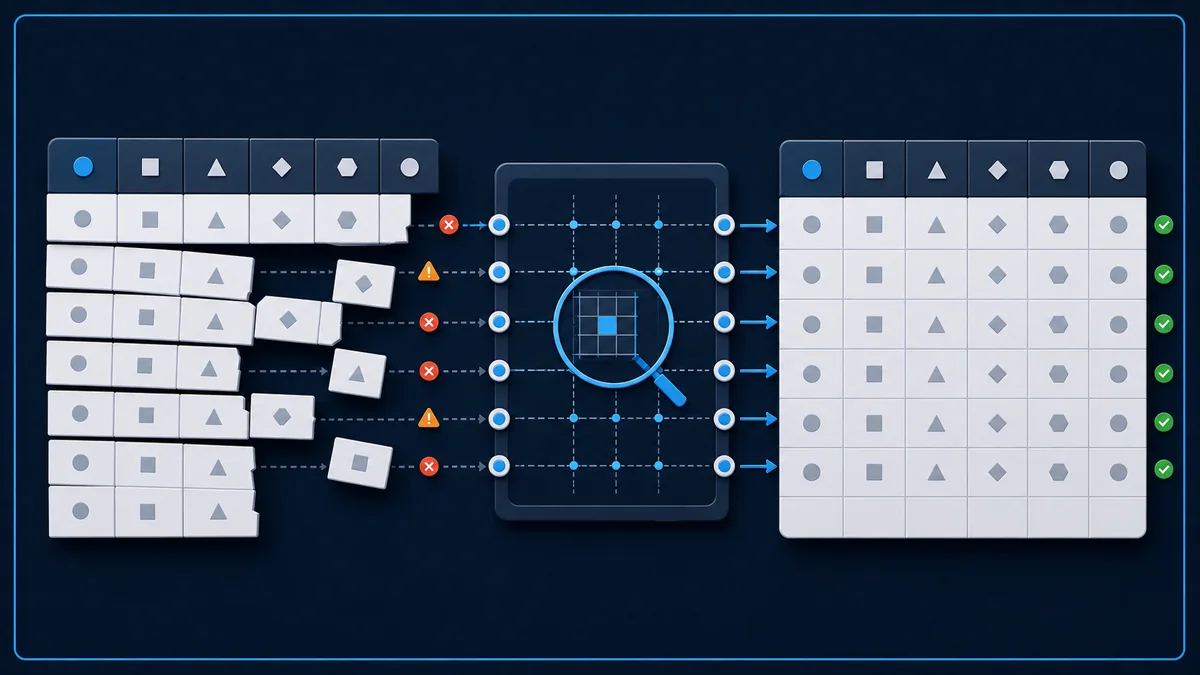
A malformed CSV is a structure problem: rows no longer describe the same fields consistently, headers are ambiguous, or quoting and separators make the parser lose track of where one field ends and the next begins. Start by locating the first structural inconsistency rather than rewriting the whole file.
Nablyx processes one CSV locally in your browser without uploading it, up to 100 MB; it writes cleaned.csv as UTF-8 CSV with the selected output delimiter. It can normalize mechanical structure and salvage an unclosed final quote, but it cannot reconstruct values already missing or truncated; the first-party cap and streaming evidence is recorded in docs/tool-audit/batch-a.md.
Find the first row that stops matching the header
Compare the header with several rows above and below the point where an import fails. A healthy table has the same logical fields in the same order, even when a field contains punctuation or a line break inside quotes.
A row whose comma needs quoting
customer_id,name,note
C-31,Riley,"priority, west"
C-32,Jordan,call tomorrow
If a comma inside priority, west is not quoted, a reader can treat it as another field and shift the rest of that row. An unclosed quote can be worse because later lines may be absorbed into the same field.
Do not “repair” uneven rows by automatically deleting extra values or padding every short row. First establish whether the row is truly missing data or whether the parser was confused by a delimiter or quote inside the text.
Header problems are structural too
Duplicate, blank, or whitespace-only headers make downstream mapping ambiguous. For example, two columns both called status do not tell an importer which value belongs to which destination field.
Rename headers deliberately using the meaning of the data, not generic suffixes unless those suffixes are acceptable to the receiving system. Check that the final header names match the import schema you actually need.
Clean invisible clutter only after you know what it means
Leading or trailing whitespace can matter. In a free-text note it may be harmless; in an ID or lookup key it can cause a mismatch. Empty rows between records may also confuse strict importers.
A BOM at the very start of the file can appear as an unexpected prefix on the first header in software that does not handle it as intended. That is different from widespread mojibake across the file.
The safe question is always: “Is this character part of the data, or formatting noise introduced by export or editing?”
Delimiter mistakes can imitate broken rows
Before changing row contents, confirm the actual field separator in a text editor. If every line uses semicolons but the reader expects commas, the file may look broken while its structure is internally consistent.
If the file uses more than one separator inconsistently, identify where that change begins and whether it came from a manual edit, concatenated exports, or a field that should have been quoted.
When a cleaner is appropriate
Use a CSV cleaner after you have confirmed that the problem is mechanical structure: stray whitespace, blank rows, straightforward delimiter normalization, or header cleanup that you can verify in a preview.
The Nablyx cleaner makes a first pass over the file to learn its shape, including the widest row, and a second pass to write the cleaned output. That matters for ragged files: values in a row that is wider than the original header are not silently discarded; the cleaner expands the header with generated column names so those values still have a destination.
It also allows an unclosed quote on the final record to be salvaged instead of losing that record, and reports the salvaged row in the cleanup summary. That is a repair worth reviewing in the preview because the tool can preserve the record, but it cannot know whether the missing closing quote was intentional.
Clean the CSV after confirming the structural issueWhen the cleaner is the wrong tool
Do not use structural cleanup to solve unreadable characters; that is an encoding problem. Do not use it to guess how columns should map into another system. And if records are genuinely missing, fields have been overwritten, or quoted text has already been truncated in the source, cleanup cannot recreate the lost values.
For a high-stakes import, keep the original file, repair a copy, and compare representative records before replacing the source.
See the transformation
Structural noise is repaired without hiding the changes.
Extra spaces, blank rows, and uneven columns are cleaned up into a consistent CSV.
customer_id ; name ; email

1042 ;  Alex  ; alex@example.com
1043 ; Sam ; sam@example.com ;
customer_id,name,email
1042,Alex,alex@example.com
1043,Sam,sam@example.com
✓ Rows and columns are consistent
Need to do this now?
Clean a structurally malformed CSVRelated tools
Open the tool this guide is about, or explore a related one.
- Clean and fix CSV files — no uploadRepair common CSV problems including wrong delimiters, uneven rows, empty lines, whitespace, BOM markers, and duplicate headers.
- Validate CSV files online freeScan a CSV once for structural, encoding, header, delimiter, and whitespace problems without changing the file.