
How to Compare Two CSV Files (Without Excel)
A practical guide to comparing two CSV exports by key column, spotting added, removed, and changed rows without spreadsheet gymnastics.
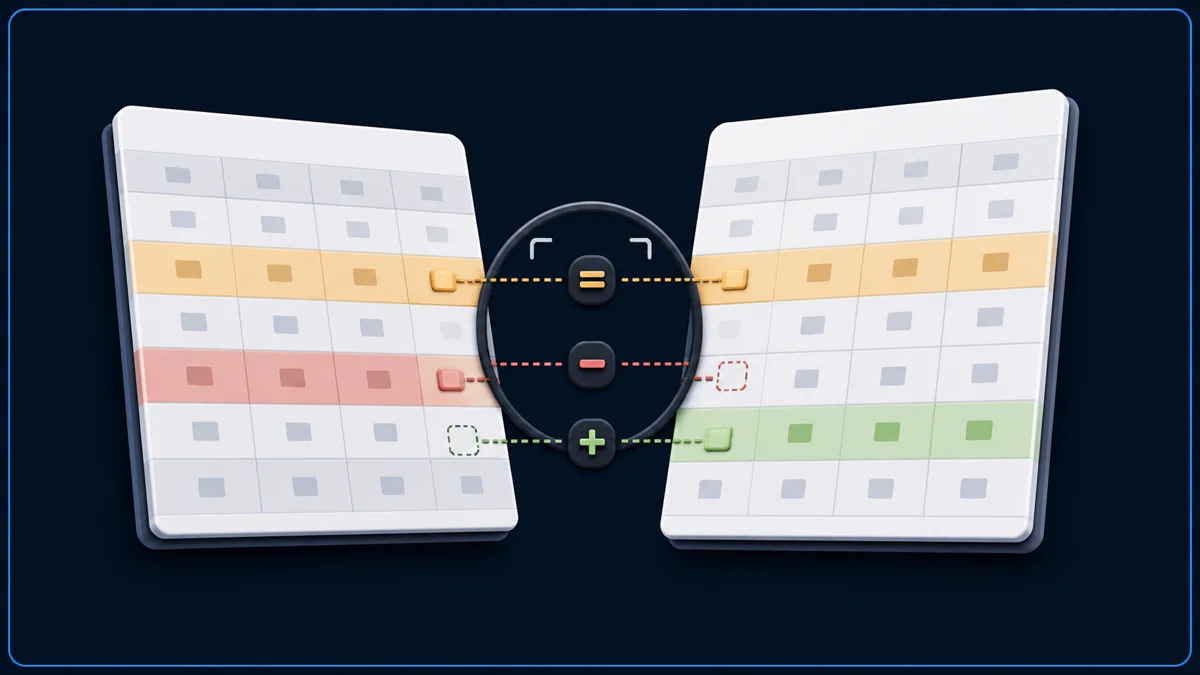
To compare two CSV files, match rows with a stable key such as a customer ID, SKU, or email, then separate the result into added, removed, changed, and unchanged rows. Compare values by column name rather than row position so inserted rows or reordered columns do not create false differences.
Nablyx accepts two CSV files and produces a downloadable comparison of the rows that were added, removed, or changed. Both files are processed locally in your browser and are not uploaded; each CSV can be up to 200 MB. The first-party evidence in docs/tool-audit/batch-a.md records the 25 MB-per-file, 50 MB-total boundary and the streaming feasibility coverage behind it.
When you actually need a CSV comparison
The most common case is checking two exports of the same dataset taken at different times: a product catalog before and after a supplier update, a customer list before and after a CRM sync, or a pricing sheet before and after a review cycle.
It's also useful for validating a migration — export from the old system, export from the new one, and confirm nothing was dropped or corrupted in transit.
Original CSV
Updated CSV
Changed row
Customer 1001 changed plans, 1004 disappeared, and 1006 is new — three distinct events a plain visual scan can easily miss in a larger file.
Pick a stable key column first
A CSV comparison is only as good as the column you match rows on. Row position isn't reliable — a single inserted or deleted row shifts everything below it and makes an unrelated diff look huge.
- 01
Find a unique column
customer_id, SKU, or email — a value that appears exactly once per file.
- 02
Check both files use it consistently
The same column name and format in the old and new export.
- 03
Combine columns if needed
If no single column is unique, pair two — email plus company, for example.
If you're not sure a column is truly unique, count duplicates first. A key with even a few repeated values will silently mismatch rows during comparison.
What a good comparison actually reports
A useful result separates rows into four groups: added (present only in the new file), removed (present only in the old file), changed (same key, different values in one or more columns), and unchanged. Seeing exactly which columns changed for a given row, not just that "something" changed, is what makes the result actionable.
| Status | Meaning | Included in download |
|---|---|---|
| added | Row appears only in the second file | Included |
| removed | Row appears only in the first file | Included |
| changed | Same key in both files, at least one column differs | Included, with per-column before/after |
| unchanged | Same key and identical values across every column | Counted in summary, not included |
The downloaded comparison keeps the rows that need attention. It includes added, removed, and changed rows, while unchanged rows stay in the on-screen summary.
Reading the on-screen results
The comparison workspace shows the first rows of each category. The summary tells you how many rows were added, removed, changed, or unchanged. For changed rows, the preview shows the old and new values side by side. Download the result when you want to review the changed rows outside the tool.
Common traps that produce false differences
Reordered columns between exports will confuse a naive row-by-row text diff even when the data is identical — compare by column name, not column position. Trailing whitespace, inconsistent casing, and different null representations (empty string vs. NULL vs. "N/A") also generate noise that isn't a real change.
Character encoding matters too: a file saved as Windows-1252 and one saved as UTF-8 can look different even with identical content if the tool doesn't normalize encoding first.
Cell values must match exactly, including spaces and letter case. Alice and alice are different, and NULL is different from an empty cell. Clean the input files first if those differences are not meaningful to you.
When to use a related tool instead
- The two files have different column names: run the CSV column mapper first to align the headers, then come back.
- You have one file and want unique rows: use remove CSV duplicates.
- You want every row from both files joined on a shared key, not just the differences: first choose the right CSV join and key.
- The data is JSON: convert with JSON to CSV or compare directly with JSON diff.
See the transformation
A useful diff separates every kind of change.
See changed, added, and removed rows separately so you know exactly what needs attention.
Need to do this now?
Compare your CSV filesRelated tools
Open the tool this guide is about, or explore a related one.
- Remove duplicate CSV rows online freeChoose the columns that define a duplicate, preview the cleanup, and download both the cleaned CSV and removed rows.
- CSV column mapper and renamerRename, reorder, and remove CSV columns before importing data into a CRM, store, database, or accounting system — without uploading your file.